Speech Conditions
Speech Recognition
The Speech Recognition condition checks whether the user speaks a phrase similar to one of the expected phrases. It uses the on-device Speech Recognition (Whisper) runtime to transcribe the microphone audio and compares it with the target phrases. The condition is satisfied when one of the phrases is recognized with at least the minimum confidence (or when the condition is skipped).
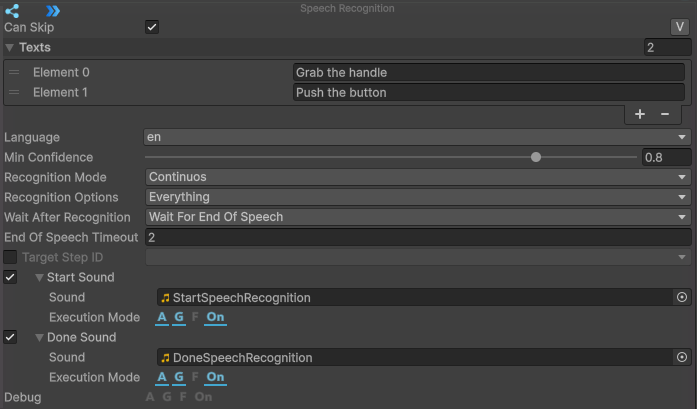
| Property | Function |
|---|---|
| Can Skip | Allows the condition to be skipped. |
| Texts | The list of phrases to recognize. The condition succeeds if the user says any of them. |
| Language | The language to recognize. Leave empty for automatic language detection. |
| Min Confidence | The minimum confidence (0–1) required to accept the recognized phrase. Default is 0.8. |
| Recognition Mode | Continuos recognizes continuously while the user is talking; OnMute evaluates when the user stops talking. |
| Recognition Options | Flags that tune the comparison: Ignore Punctuations (ignore punctuation when matching) and Middle Sentence (also match the phrase when it appears in the middle of a longer sentence). The inspector shows Everything when both are enabled. |
| Wait After Recognition | Wait For End Of Speech keeps listening until the user stops talking after a phrase is recognized; No Wait completes as soon as the phrase is recognized. |
| End Of Speech Timeout | (only with Wait For End Of Speech) Maximum time, in seconds, to wait for the user to stop speaking after a phrase is recognized. If no silence is detected within this time, recognition is forced to complete. Default is 2. |
| Target Step ID | When enabled, lists the condition under the specified step. |
| Start Sound | Optional sound played when recognition starts, with the execution modes it applies to. |
| Done Sound | Optional sound played when a phrase has been recognized, with the execution modes it applies to. |
| Debug | Enables debug feedback for the selected execution modes. |
note
The recognition runs on-device with Whisper; the models live in StreamingAssets/WEAVR/Whisper/. See the Speech Recognition page for details on the models and the microphone.