Speech Recognition
WEAVR can transcribe the user's voice at runtime using an on-device Whisper runtime. Transcription runs locally, so spoken input can be used inside a procedure (for example to answer a question or to talk to DAISY), and WEAVR AI voice prompts work, without sending audio to an external transcription service.
Voice Manager
The Voice Manager is the runtime component that handles speech: it records the audio from the microphone and communicates with Whisper to transcribe it. It is included on the Weavr prefab (under Managers), so it is already present in a scene set up with WEAVR, and it acts as a single shared service that the conditions, DAISY and WEAVR AI all use to capture and transcribe voice.
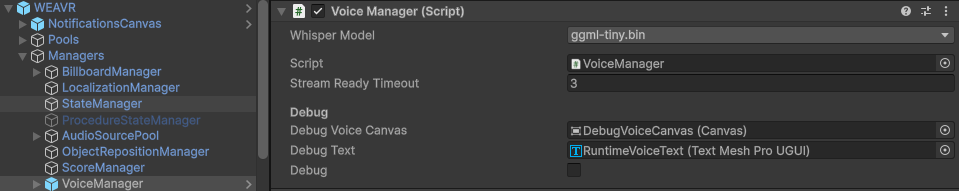
| Property | Function |
|---|---|
| Whisper Model | The Whisper model used for transcription (default ggml-tiny.bin). The dropdown lists the ggml models found in StreamingAssets/WEAVR/Whisper/; to add a new one, just drop its ggml file into that folder and select it here. |
| Stream Ready Timeout | Maximum time, in seconds, to wait for the transcription stream to become ready (default 3). |
| Debug | When enabled, shows a debug canvas with the live transcription text (the Debug Voice Canvas / Debug Text), useful while authoring and testing. |
Models
Whisper uses ggml model files placed in the project's StreamingAssets/WEAVR/Whisper/ folder. WEAVR ships with ggml-tiny.bin as the default model. You can add other ggml model files (for example a larger, more accurate model) to that folder and select them through the Voice Manager's Whisper Model Name field.
GPU acceleration is provided by the underlying Whisper runtime depending on the platform; WEAVR does not expose a separate GPU/acceleration setting.
Microphone
Speech is captured from the microphone as PCM audio and transcribed locally. In WEAVR AI, the microphone device used for voice input is selectable in the assistant settings.
End-of-speech and confidence
Speech recognition can wait for the user to finish speaking and uses a confidence threshold to decide whether the expected phrase was actually understood before the step proceeds. These options are configured on the Speech Recognition condition:
- Min Confidence — the minimum confidence required to accept the recognized phrase.
- Wait After Recognition / End Of Speech Timeout — whether to keep listening until the user stops talking after a phrase is recognized, and for how long.
Using speech in a procedure
Speech recognition is used through the Speech Recognition exit condition, which checks whether the user said one of the expected phrases and advances the step when they do.